Ask. It’s done.
A complete report from a single question was always the dream. Now it comes back in minutes, written from your own research, on your own machine.
- Build a guidance tracker for NVDA, with what our previews expected
- Is the rumor that Microsoft cut its GB300 order true?
- Comps for NVDA against its closest peers
- How has NVIDIA’s China commentary changed over six quarters?
- What would a 10% move in TSMC do to the book?
- Hyperscaler capex and cloud growth, last four quarters
- Who are NVIDIA’s largest holders, and what are the stakes worth?
- What is driving the GB300 ramp?
After closely comparing five vendors, Treasurer delivered the most accurate figures and analysis.
AI Lead, Data & Content · TheBell




Start every morning briefed.
Core reads what came in overnight, marks your book, and writes the brief before the open.
Every other research AI gives every fund the same model.
Core gives you yours. Six places where that shows.
| Capability | Other research AI | Core |
|---|---|---|
| A model trained on your research | Not offered: One model, shared by every customer | Built in: Your model, trained on your analysts’ work |
| Runs in your office | Partial: Their cloud; a single tenant at best | Built in: A machine in your office. Nothing leaves. |
| Knows your book | Not offered: Documents only | Built in: Marks the book every morning and writes the brief |
| Rumor check | Partial: A thesis tested against documents, at best | Built in: A verdict on each claim, with a probability, from your notes and data |
| Every number traced | Partial: Citations | Built in: Citations, plus a replay of every tool call and data timestamp |
| Asian filings | Partial: English first; global filings | Built in: DART in full text; Korean, English, Chinese and Japanese |
Your data. Your model. Your machine.
Nothing leaves the firm. Security your IT and compliance teams can trust.
Your data
Documents, the book and every answer stay on a machine in your office.
- Nothing leaves unless you choose it
- An answer log: every answer, its sources, who reviewed it
Your model
Trained on your research, and accounted for.
- A model card: which model, where, and its hash
- Controls mapped to the SFC GenAI principles
- An inspection pack in one download
Your machine
NVIDIA hardware you own, on a desk or in your rack.
- Built on NVIDIA’s stack
- Treasurer is an NVIDIA Inception member
Three ways to run it
Start small.
Core and your documents on a small machine in the office. Questions go to a cloud model under your own agreement with that provider.
- Chip
- Apple M4 Pro
- Memory
- 48 GB unified
- Model
- Cloud, under your own agreement
- Leaves the firm
- Your questions
Your own model, on a desk.
Indexing, the brief and rumor checks run on the Spark. Only what you type into chat goes to a cloud model.
- Chip
- NVIDIA GB10 Grace Blackwell
- Memory
- 128 GB unified
- Model
- Local, up to 200B parameters
- Leaves the firm
- Chat messages
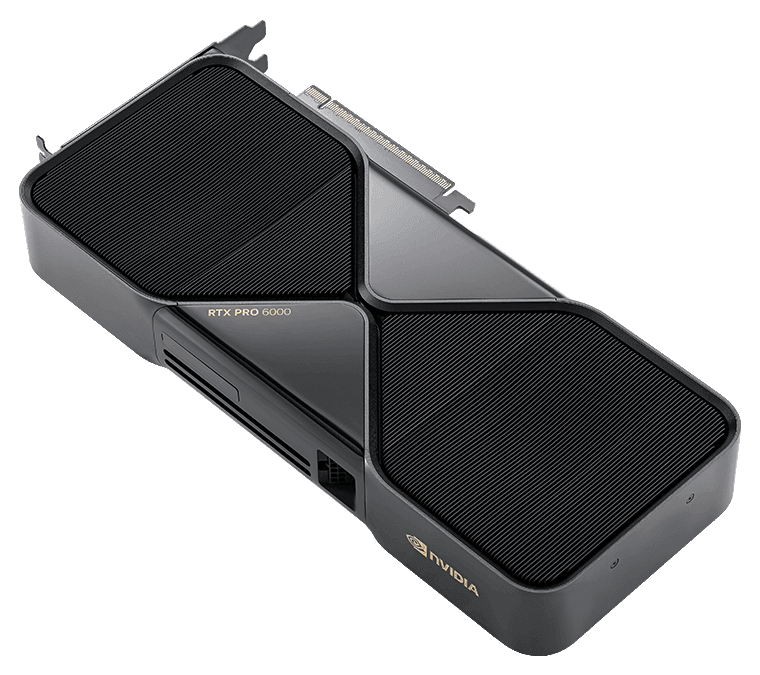
Everything in the office.
Documents, model and chat on your own hardware. The model card and the answer log record exactly what ran.
- GPU
- NVIDIA RTX PRO 6000 Blackwell
- Memory
- 96 GB GDDR7
- Model
- Local, chat included
- Leaves the firm
- Nothing
See Core on your own research.
A 30 minute demo, then a pilot on your own documents.
contact@treasurer.co.kr
Core is built by Treasurer, the AI platform for finance.
Treasurer builds the engine that collects, refines and reasons over financial data, and the products on it: AlphaLenz, ARIA and Findle. Core brings that engine inside a fund’s own walls.
treasurer.co.kr ↗
Treasurer is a member of NVIDIA Inception, NVIDIA’s program for AI startups building on its platform. Core is built on NVIDIA’s stack and runs on NVIDIA hardware, from a desktop DGX Spark to your own GPU servers.